

The problem, plain and simple
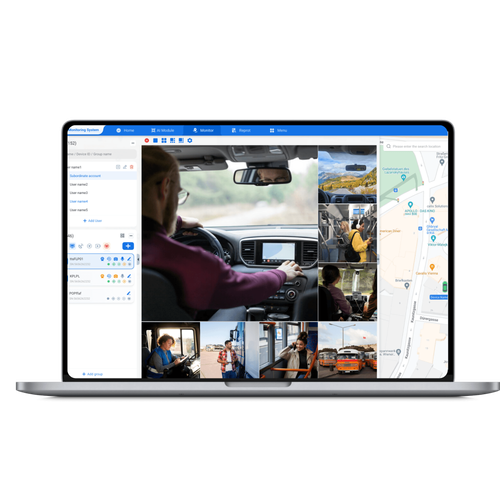
Fleets lose minutes, data, and sometimes trust because critical telematics components were treated like optional extras. The real trouble starts when a driver, a device, or an API has more access than it needs. That’s why when operators pick a fleet management solution they also need to inspect how identities, devices, and data are controlled — the same inspection that should happen for any fleet management gps tracking layer feeding the dashboard. This piece takes a problem-first view: identify the pain, then map to specific fixes you can apply without consultants and long waits.
Where things break — common failure modes
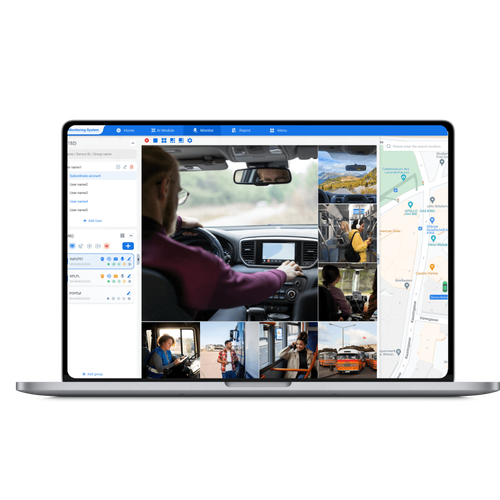
Start by spotting the patterns. Problems repeat across fleets because the underlying causes are simple and human.- Unauthenticated or weakly authenticated endpoints: default credentials, shared accounts, or tokens that never expire.- Monolithic access: one admin account controls everything with no segmentation.- Unencrypted telemetry in transit or at rest, or encryption that’s half-baked (e.g., only HTTPS for the web UI while device-to-cloud traffic is plaintext).- Fragile update chain: devices accept firmware updates without signed packages.- APIs exposed with broad scopes and no rate limiting.- No audit trail: changes happen, no one knows who did what or when.- Data hoarding: location logs retained forever, increasing leak risk and privacy exposure.
Concrete fixes you can apply this week
Fixes aren’t magic. They’re a checklist you follow until the problems stop reappearing.- Enforce unique identities and short-lived credentials. Use mutual TLS or strong API tokens with scopes.- Apply least privilege and role-based access control for operators, maintenance, and third parties.- Sign firmware and require verification on the device before install.- Encrypt telemetry end-to-end and store keys in a hardware-backed key manager.- Segment networks so telematics devices can’t reach internal corporate services directly.- Enable comprehensive logging and ship those logs to an external SIEM; keep retention appropriate, not infinite.- Implement geofence-based privacy masks for non-essential tracking windows (off-shift, sensitive locations).- Use device attestation and tamper-evidence to flag suspicious hardware behavior.
Short-term vs long-term trade-offs
Quick wins get you breathing room; structural changes stop repeat incidents. Quick wins:- Rotate default credentials and enforce MFA on interfaces.- Push signed firmware immediately.Structural work:- Move to an identity provider and apply RBAC across products.- Build a secure update pipeline and test rollback scenarios.Expect short outages during structural work. That’s normal; it’s better than hidden breaches later.
Vendor selection and integration realities
Vendors look good in demos, but you need to ask tactical questions.- How do they authenticate devices at scale?- Do they support signed firmware and hardware attestation?- Can RBAC be enforced across API calls and consoles?- Where and how long do they retain raw GPS traces?- What incident response playbook do they use?Demand technical answers, not marketing gloss. A vendor who can show a clean chain of custody for a device update and an external audit of their APIs is far more useful than one with polished dashboards alone.
Where teams usually stumble
Mistakes repeat because teams treat security as a bolt-on.- Patching on a schedule instead of listening to telemetry for signs of compromise.- Trusting a cloud console implicitly instead of verifying that device-to-cloud channels are secure.- Over-collecting location data “just in case” instead of thinking through retention and access rules.- Assuming a single vendor will secure every layer; integrations introduce risk and need their own policies.
A pragmatic example
I worked with a 200-truck regional fleet in Texas that kept losing time to incorrect geofence alerts and driver privacy complaints. We tightened device authentication, shortened audit windows for sensitive location data, and isolated telematics traffic from the company network. Result: fewer false alerts, clearer incident logs, and no new privacy complaints in six months. That kind of hands-on pruning is what separates good intent from practical results.
Checklist for your next procurement or audit
Use this to avoid the obvious traps.- Require signed firmware and proof of verification.- Demand device attestation and unique identities.- Insist on scoped APIs and short-lived tokens.- Check data retention policies and ask for configurable retention.- Verify logging to an external, immutable location.- Confirm physical tamper detection options for hardware.- Test emergency access workflows and revoke privileged sessions automatically.
Final thought
Problems show up because access and data weren’t treated as assets that need guardrails. Solve that and you stop the same incidents from cycling back. Practical work—firmware signing, scoped credentials, readable audit trails—creates both security and predictable operations. If you want a partner that focuses on those exact, tangible controls rather than promises, consider how BSJ organizes device identity, update integrity, and access control so fleets stop fixing the same hole twice.

